webmotivated

  • AI Receptionist
  • Contact
  • Success Stories
  • About
  • Home

Business-Critical Rail Data Pipelines

Goal

Modernise business-critical rail data processing by replacing legacy desktop and manual workflows with reliable, scalable and governed AWS data pipelines.

The programme needed to move important operational datasets — including ticket sales, ticket scans, reservation availability, customer-experience feeds and delay-repay data — onto a centrally managed cloud platform without disrupting existing reporting or downstream consumers.

The objective was not simply to “move data to AWS”. It was to create production-ready data services that could be trusted, monitored, maintained and extended by the wider engineering team.

Role

As a Contract AWS Data Engineer, I designed, built, tested and operationalised production data pipelines across LNER’s AWS data platform.

My work covered the full delivery lifecycle: understanding existing business processes, analysing legacy outputs, designing cloud-native replacements, building ingestion and transformation logic, implementing data-quality controls, supporting user acceptance testing, deploying infrastructure and resolving production issues.

  • Legacy-to-cloud modernisation. Replaced Alteryx and manually operated data processes with automated AWS pipelines designed for central ownership, scalability and long-term maintainability.
  • Production data engineering. Built ingestion and transformation workflows across APIs, files and databases using Python, SQL, PySpark, AWS Glue, Lambda, Step Functions, S3, Athena and related AWS services.
  • Incremental and historical processing. Designed pipelines capable of processing new data incrementally while also handling large historical backfills and safely bringing legacy history into the same curated datasets.
  • Data quality and reconciliation. Implemented completeness, uniqueness, schema and business-rule validation so data problems were detected before reaching downstream users. Outputs were reconciled against existing processes during UAT to prove that the new platform could safely replace them.
  • Production reliability. Designed restartable processing, pagination and continuation behaviour, deterministic record keys, retries and operational controls so pipelines could recover safely from failures rather than requiring manual rebuilding.
  • Secure external data delivery. Built controlled outbound feeds to external partners using encryption, managed credentials and restricted cloud access rather than exposing internal data stores directly.
  • Infrastructure and deployment. Delivered cloud configuration and environments using Terraform/Terragrunt and CI/CD, supporting repeatable deployment across development, staging and production.
  • Stakeholder collaboration. Worked directly with engineers, analysts, data providers and business users to understand requirements, resolve discrepancies and turn existing operational processes into maintainable technical solutions.
  • Technical ownership and documentation. Produced detailed pipeline and operational documentation so systems could be understood, supported and extended after delivery.

The work ranged from straightforward scheduled extracts to complex multi-stage pipelines combining incremental APIs, historical data, transformation, quality controls and curated AWS data stores.

Capability

The resulting capability moved business-critical processing away from individually operated desktop workflows and into centrally managed cloud services.

Business Impact

  • Ticket scan data. Replaced a legacy Alteryx process with a governed AWS pipeline, giving teams a more reliable source for ticket-scan analysis and reporting. Historical migration covered 100+ million scan records.
  • Ticket sales data. Brought historical and ongoing ticket-sales data into one automated cloud pipeline, improving consistency for reporting and reconciliation while reducing reliance on manual processing.
  • Reservation and ticket availability. Replaced legacy reservation workflows with a cloud-based data service, giving the business more reliable visibility of seat and ticket availability across services, journeys and booking horizons.
  • Customer-experience punctuality feed. Automated the daily delivery of disrupted-train data into the customer-experience platform, supporting timely analysis of how disruption affects passenger experience and removing dependence on the legacy feed.
  • Delay Repay data delivery. Automated the daily flow of rail transaction data into Delay Repay processing, replacing repeated manual extraction with a faster, more reliable and controlled data feed.
  • Safer migration. Reconciled new cloud outputs against existing processes before cutover, reducing the risk of disrupting reporting or downstream users.
  • Better resilience. Built pipelines to recover safely from failures, rerun where needed and reduce manual intervention.
  • Stronger data quality. Embedded validation so incomplete, duplicate or invalid data could be caught before reaching analysts, reports or external consumers.
  • Easier future change. Replaced individually operated desktop workflows with centrally managed, documented cloud services that were easier to support and extend.

How

  • Scalable cloud processing. AWS-native services supported growing data volumes, historical backfills and recurring production workloads.
  • Built-in data quality. Completeness, uniqueness, schema and business-rule checks were embedded into processing.
  • Recoverable processing. Incremental state, deterministic keys and restartable workflows supported safe continuation after interrupted runs.
  • Secure data delivery. Encryption, AWS IAM, Secrets Manager and governed external delivery patterns protected business data.
  • Operational transparency. Logging, orchestration and documented run behaviour made failures easier to diagnose and recover.
  • Maintainable engineering. Infrastructure as Code, CI/CD and reusable platform patterns supported repeatable deployment across environments.
  • Controlled migration. Legacy outputs were reconciled against new AWS pipelines before production adoption.

Tech Stack

  • Programming & Data Engineering: Python, SQL, PySpark
  • AWS Data Processing: AWS Glue, Lambda, Step Functions
  • AWS Storage & Analytics: S3, Athena, Redshift
  • Data Lake Technologies: Apache Hudi, Parquet
  • Orchestration & Scheduling: AWS Step Functions, EventBridge
  • Security & Access: AWS IAM, Secrets Manager, Lake Formation
  • Infrastructure as Code: Terraform, Terragrunt
  • DevOps: Git, CI/CD, GitHub Actions
  • Data Integration: REST APIs, JDBC, CSV, JSON, Parquet, SFTP
  • Data Quality: Schema validation, completeness checks, uniqueness controls, reconciliation, deterministic record keys
  • Secure Delivery: PGP encryption, SSH/SFTP, cross-account AWS delivery
  • Collaboration & Delivery: Jira, Confluence, technical documentation, UAT and stakeholder reconciliation

Year

2026
Filed Under: Data Pipelines

Cookie Consent Log

Goal

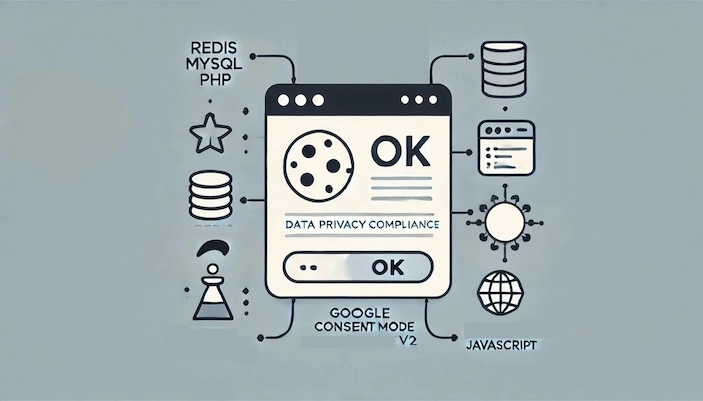
Empower businesses to ensure privacy compliance by seamlessly capturing, documenting, and preserving proof of cookie consent in line with the latest data protection regulations and integrating with industry initiatives like Google Consent Mode v2.

Role

As the lead developer, I designed, implemented and deployed a robust, scalable solution for capturing and managing cookie consent. My role spanned end-to-end system architecture, backend development, and seamless integration with front-end interfaces to deliver a compliance-ready system tailored for modern privacy standards.

  • Solution architecture. Designed and implemented a scalable pipeline leveraging Redis for real-time data capture and MySQL for long-term consent storage, ensuring fast, reliable processing across high-traffic environments.
  • Front-end and backend integration. Combined JavaScript and PHP to enable real-time synchronization between cookie banners and server-side logging, delivering a secure and seamless user experience.
  • Automated data workflows. Built cron jobs to move data from Redis to MySQL, ensuring data retention policies align with compliance requirements while enabling detailed reporting.
  • Privacy compliance enablement. Integrated with Google Consent Mode v2, ensuring the system supports the latest privacy regulations and puts user control at the forefront.
  • Custom logging and validation. Developed robust backend logic for consent data validation, rate limiting, and intent analysis, ensuring data accuracy and regulatory compliance.

Capability

This solution acts as an intelligent, automated system for capturing and managing cookie consent data, ensuring compliance with modern privacy regulations while maintaining a seamless user experience for website visitors.

  • Consent Data Capture: Tracks user consent actions—both explicit and implicit—by integrating seamlessly with your website’s cookie banner. This ensures every interaction is logged securely and accurately.
  • Speed and Reliability: A robust combination of fast in-memory processing (Redis), rate limiting, and PHP validation ensures high performance, even during traffic spikes.
  • Data Synchronization Pipeline: Smart orchestration of cron jobs moves consent data from Redis to MySQL, ensuring long-term storage and compliance tracking, enabling detailed reporting and reducing reliance on third-party cookies.
  • User Control & Privacy Regulation Compliance: Full compliance with privacy standards like Google Consent Mode v2 allows users to control their data while giving businesses confidence in their ability to meet GDPR and other privacy requirements.
  • Customizable and Scalable Design: Built to adapt to your specific needs with configurable cookie expiration policies, ensuring it grows with your business while remaining fast and efficient.

Tech Stack

  • Consent Management & Privacy Logic: Google Consent Mode v2, WordPress Cookie Plugin
  • Front-End Integration: JavaScript, jQuery
  • Real-Time Data Processing: Redis, PHP
  • Server-Side Validation & Logging: PHP, Predis (Redis Client)
  • Data Storage & Synchronization: MySQL, Cron Jobs
  • API Communication & Debugging: jQuery AJAX, Custom API Endpoints

Year

2024

Filed Under: AI / Apps, Data Pipelines

De-Risked Public Sector Data

Goal

Future-proof public sector client’s data management processes (collection, sharing, use, storage and publication). Consolidate data assets from multiple source systems for analysts to gain better insights and enrich their analyses.

Role

  • Developed and optimized AWS-based ETL processes: Designed and implemented 5 AWS Lambda functions and multiple AWS Glue ETL jobs, enhancing data ingestion and processing efficiency. This resulted in a 30% reduction in data pipeline execution time by automating data mapping, data asset initialization, and data preparation workflows.
  • Implemented robust data sanitization and compliance measures: Enhanced data quality and regulatory compliance by debugging and extending AWS Glue ETL jobs to perform comprehensive data sanitization, personally identifiable information (PII) identification and redaction. This ensured all data handling adhered to GDPR standards, securing sensitive information across all datasets.
  • Streamlined data migration and documentation: Authored high-level and low-level design documents and testing plans to ensure clear, maintainable code and reliable data migration processes. Developed 25 custom scripts for efficient data migration into AWS PostgreSQL, facilitating the seamless transition of critical data assets with minimal downtime.

Capability

Data-driven decision-making and reporting enabled via custom built:

  1. Data Integration: Combined data from various sources into a unified data warehouse.
  2. Data Transformation: Standardised and sanitised data for consistency and accuracy.
  3. Data Accessibility: Provided a user-friendly interface for accessing and querying data.
  4. Reporting and Analytics: Enabled comprehensive reporting and analytics capabilities.

Tech Stack

  • Python – coding language for data pipelines
  • SQL – DQL, DML, DDL
  • AWS Cloud Services
    • Aurora RDS – To host a data warehouse
    • Glue – for data pipelines
    • Lambda – serverless compute platform
    • Step Function – workflow orchestrator
    • S3 – cloud storage
    • Comprehend – Machine Learning powered, continuoulsy trained Natural Language Processing (NLP) service. Used to identify and redact the personally identifiable information (PII).
    • CodeCommit – for repository management
    • CloudShell – browser-based CLI environment
  • Apache Airflow – for orchestration of data pipelines using DAGs
  • Docker Engine / Desktop – to create containers for airflow environment and postgresql instance
  • DevOps – GitHub Actions, Terraform
  • Git – for repository management
  • Pycharm – IDE
  • Atlassian Toolset – Jira / Confluence
  • Sharepoint – content collaboration and workspace
  • Mural – content collaboration / design
  • Microsoft Visio – solution design

Year

2024

Filed Under: Data Pipelines

Social Listening Data Pipelines

Goal

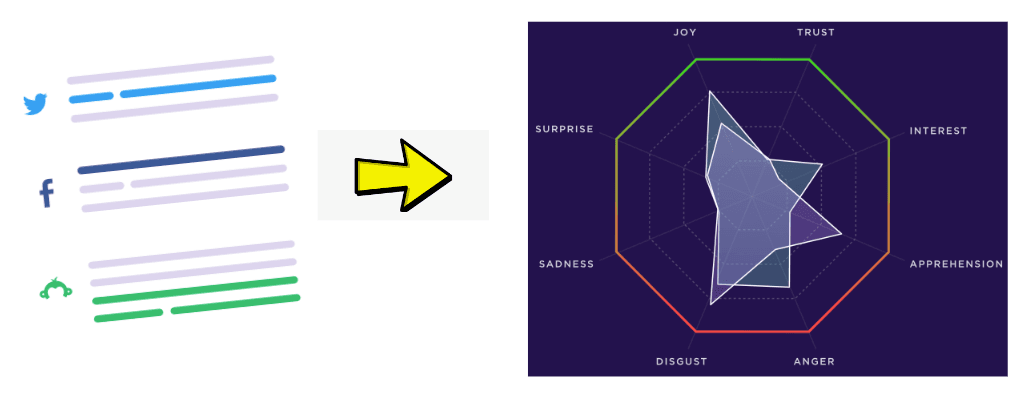
Client wanted to continuously quantify how the biggest and 200+ most polluting companies compare to each other (on the 0-100 scale) when it comes to their reputation + performance in causing less pollution + pro-activity in the space of general sustainability.

Role

  • Leveraged python OOP code across various tasks, reducing time-to-delivery by 60%. The code executes competitive benchmarking and sentiment analysis, thus improving the client’s campaign accuracy.
  • Co-developed python data pipelines for web crawling, ETL, data validation, and testing. To our client this serves as an extensive and efficient social listening system. The system scans corporate social media, annual reports for the 200+ companies, processes the data and feeds into the charts and KPIs at the front-end.
  • Quantified the reputation, sustainability and pollution reduction efforts across 200 target companies. Outcome was key in the acquisition of 2 new high-profile clients;

Capability

Multi-source and multi-keyword data pipelines driving sentiment analysis, competitive benchmarking and effective resource allocation in multinational advertising and public relations company.

Tech Stack

Python (OOP) ; PyTest ; data pipelines building (Python + Luigi) ; Regular Expressions (Regex) ; Git ; Data validation (Great Expectations); Data ETL ; Web crawling (pages and apis) ; AWS S3

Year

2022

Filed Under: Data Pipelines

Cloud Data Migration

Goal

To future-proof and centralise their data assets, client embarked on a cloud-based data migration and transformation journey.

Role

  • Supported the client’s cloud-based data migration and centralization initiative, resulting in a 25% reduction in data access time and saving 000s of pounds in annual maintenance costs by:
    • Collaborating  on PySpark and SQL-based Azure Synapse notebooks;
    • Scripting CI/CD integration for data loading, transformation, validation, and writing into the ‘Strategic Data Platform’ SDP) for HM Courts and Tribunals Service, UK Ministry of Justice.

Tech Stack

SQL ; PySpark ; Azure Data Factory (ADF) ; Synapse Analytics; CI/CD ; Regular Expressions (Regex) ; Git ; Microsoft Azure Cloud

Year

2023

Filed Under: Data Pipelines

Knowledge Extraction With Spark

Goal

Derive meaningful insights and knowledge from large volumes of text data.

Role

I developed a python and spark based tools to recognise, process and summarise untructured text data.

Capability

Highly customisable toolkit for rapid and high quality exploration of text patterns:

  • Profile unstructured text data by recognizing and quantifying either all text strings or user-defined ones.
  • Capture context variations around text patterns of interest
  • Conduct semantic grouping at scale to enhance clarity regarding patterns in text and improve the accuracy of conclusions.
  • Produce analytics-ready summarized data.

Tech Stack

Regex, Spark, Python, Big Data

FROM:

Polluted + unnecessarily dilluted view of text patterns

TO:

Contextual focus + meaningful relative scale

Year

2022

Filed Under: Data Pipelines

Quantifying Compliance in the FTSE 100 Company

Goal

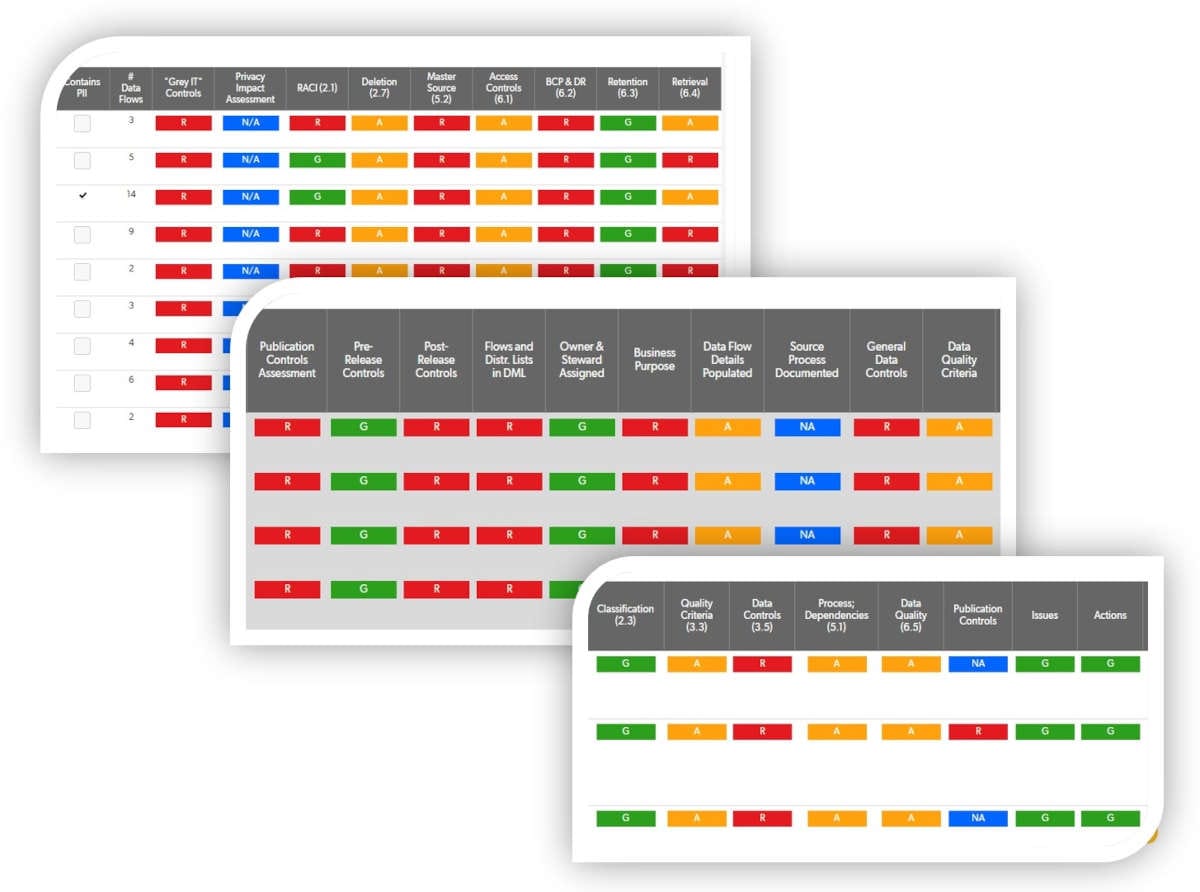
Develop a platform for gauging data BMS compliance across the company’s data landscape (1000+ of data nodes and 5000+ of data flows between them) in real time. Establish, centralise and create organisation-wide transparency by enabling the business to continuously manage the data about data (eg. information on data ownership, business purpose, data related obligations, state of their data controls, state of their data quality). Also, identify and profile data related risks, drive remedial actions.

Role

  • I have led the development of key components within the compliance apps ecosystem, which powers the creation, measurement, and automation of data management standards compliance for the UK’s electricity system operator, National Grid ESO.
  • I proposed and implemented various automated workflows (e.g., QuickBase native API, Python API, Power BI UI) to identify gaps, track progress, report findings, and initiate personalized remedial actions across over 60 business teams.
  • I translated the standards into more than 30 custom-coded KPIs, including procedures for strengthening data controls across thousands of the company’s critical and operationally critical data nodes and flows using the QuickBase native API.
  • I simplified and streamlined the user experience (UX) and user interface (UI) of the National Grid ESO’s “Data Management Library” app to ensure it aligns seamlessly with evolving business needs.
  • Despite a 2x reduction in my team’s headcount, my achievements were crucial in maintaining and improving our team’s service levels (annual NPS score up from 53 to 65).

Capability

The main app in the ecosystem – the National Grid ESO “Data Management Library” (DML) featuring:

  • 30+ live custom coded KPIs measuring compliance against
  • Data BMS standards in
  • 65 business teams owning
  • 1000+ data nodes and
  • 5000+ data flows

Tech Stack

QuickBase native API, Python Pandas, Python Selenium, Power BI, HTML5, SQL.

Year

2021

Filed Under: AI / Apps, Data Pipelines

Web Scraper

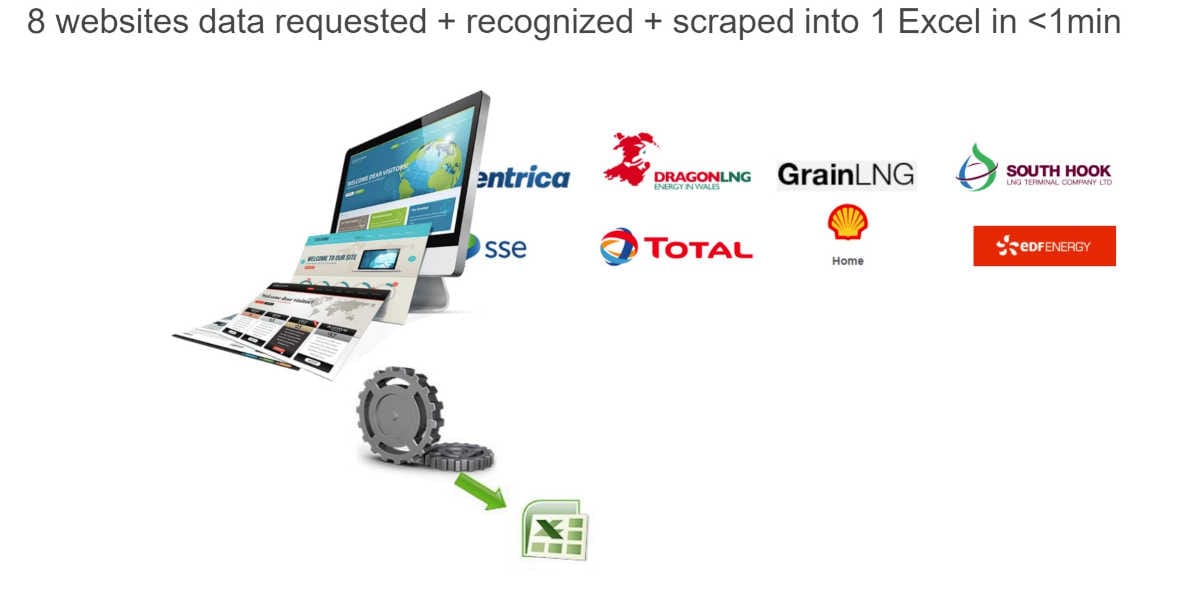
Data collection tool for producing accurate forecasts of the total supply in the UK’s natural gas market.

Goal

Client asked me to fix 3 resource drains:

  1. Time drain. Time consuming data collection.
  2. Money drain. Manually collected data was used in the natural gas demand forecasting process. Poor data quality and insufficient data collection frequency resulted in suboptimal forecasting results and significant revenue loss.
  3. Stress. Unlock new time for more rewarding work and reduce human stress.

Role

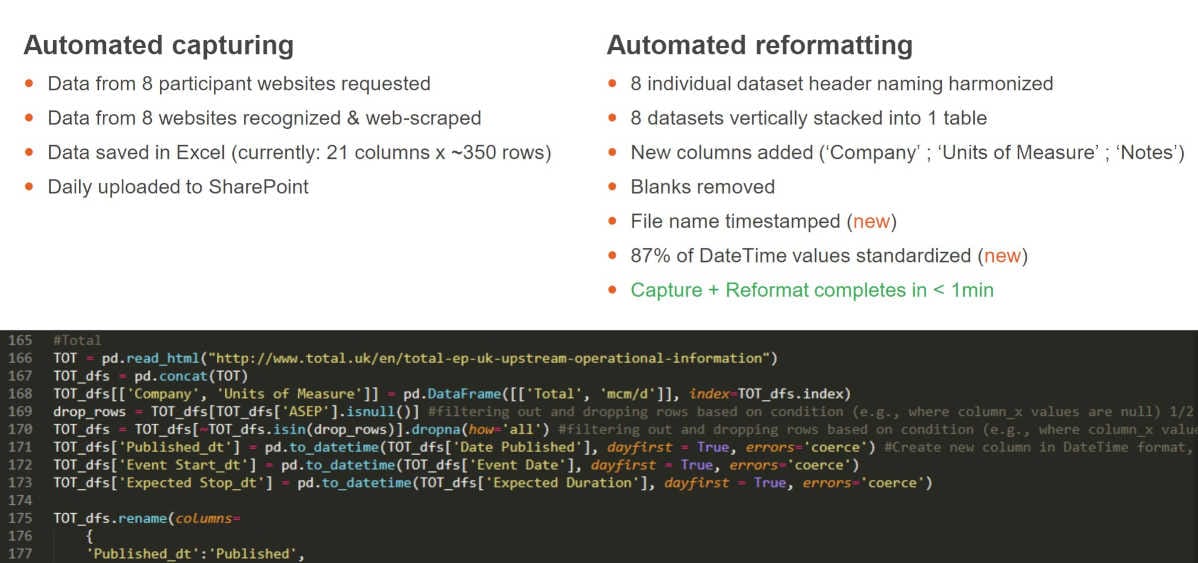
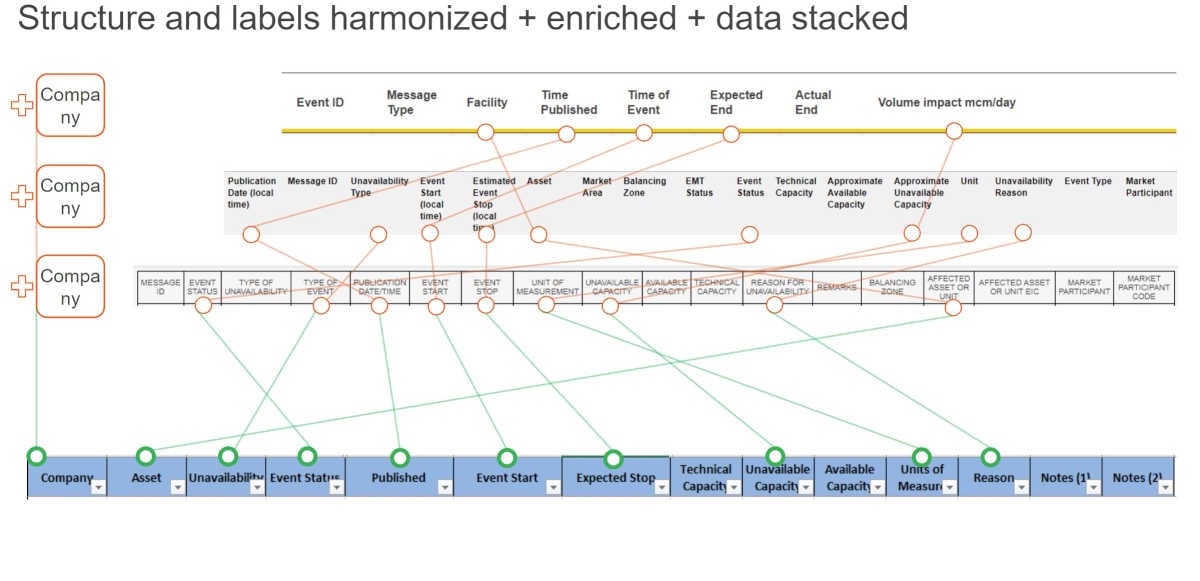
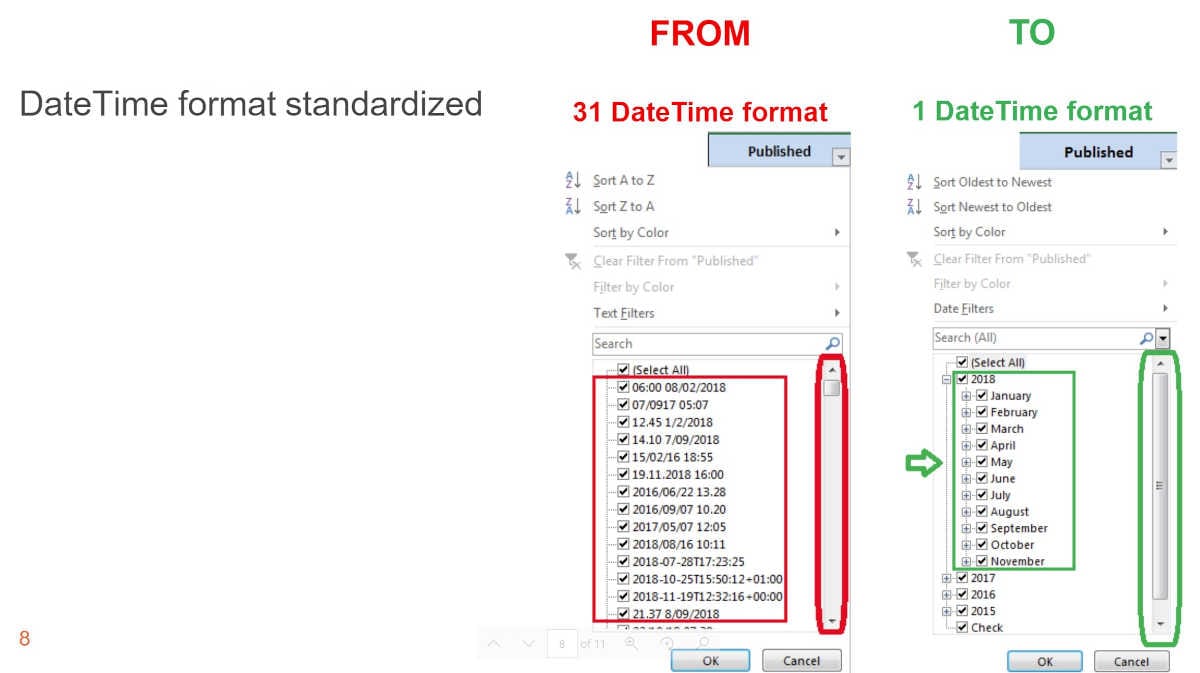
I automated tedious data processes with python (retrieval, harmonization, reformatting, sharing), saving 2 FTE hours per day, improving forecasting accuracy, maximizing company revenue, and creating more time for rewarding work.

Capability

I delivered 3 benefits for the client:

  1. Time gain. 2 hours (1 FTE equivalent) of time savings per day;
  2. Money gain. Better data quality, higher frequency and faster collection process significantly improved demand forecasting deliverables and protected key revenue stream.
  3. Reduced human stress. New time for more rewarding work unlocked / stress reduced.

Preview

Tech Stack

Python, API development, Database design, Data pipelines, ETL, Web scraping, Data quality automation.

Year

2019

Filed Under: Data Pipelines

CRUD Operations

Goal

Enable local church community to self-manage rotas for a smooth mass service.

Role

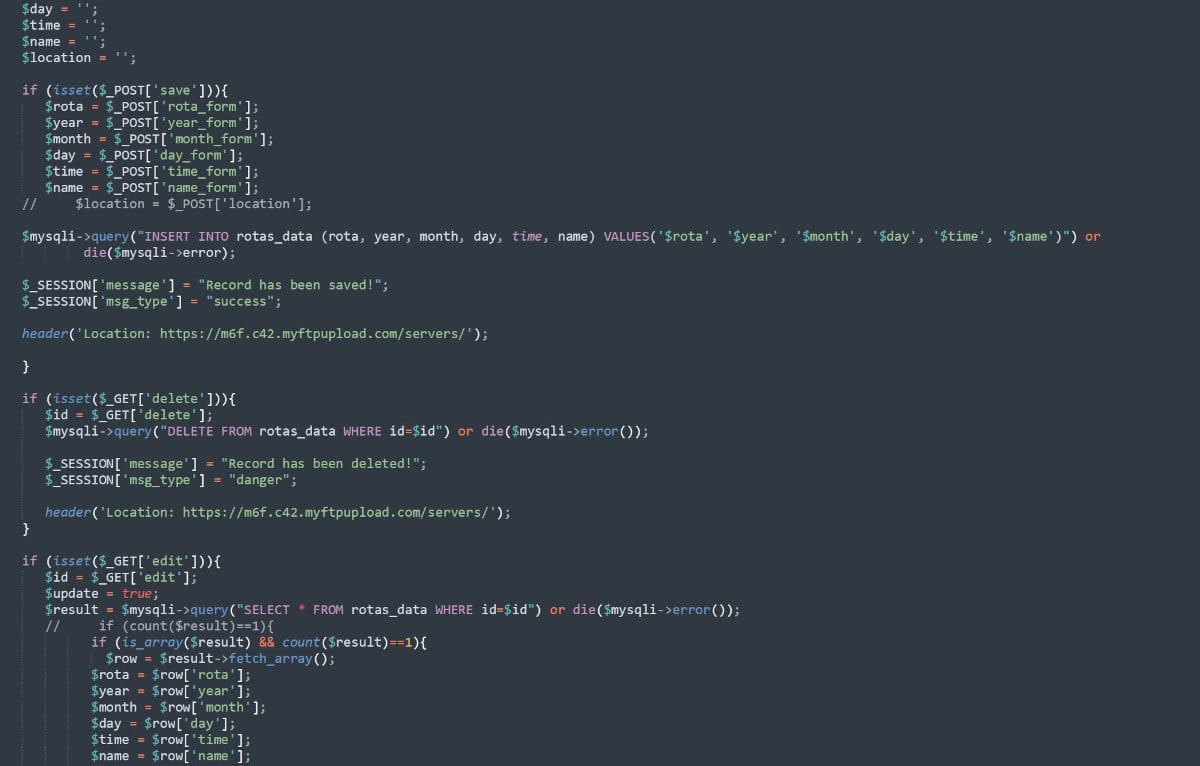
I developed a CRUD app to handle create-read-update-delete operations on a community website.

Capability

A web app featuring:

  • functionality to create – read – update – delete rotas info
  • permissions

Skills

PHP, HTML5, CSS3, JavaScript

Year

2020

Filed Under: AI / Apps, Data Pipelines

Bulk Downloader

Goal

Power reporting process to create a lot of visibility and impact + deliver time and money savings on production.

Role

I developed a python tool to automate tedious data process with python (retrieval + sharing) for the FTSE 100 company. This has boosted their reporting efficiency + unlocked new time for a more rewarding work.

Capability

Produces a user-friendly and comprehensive presentation to the top management. Python tool actions below for 100+ reports:

  • authenticates access to an in-house web-based system
  • opens necessary pages
  • downloads page contents as offline HTML files
  • uploads HTML files onto SharePoint site

Tech Stack

Python, Microsoft SharePoint.

Year

2021

Filed Under: Data Pipelines

  • 1
  • 2
  • Next Page »

CONTACT

  • 24/7 Support: Speak with our voice AI agent Lisa, +44 7 87875 5945.
  • Discovery Call (20 mins): Book a no-obligation chat to discuss AI automation.
  • Email us: We respond within 48 hours.

GO TO

AI Receptionist Success Stories About Home

SOCIALIZE

  • LinkedIn
  • YouTube

© Copyright 2020 · WEBMOTIVATED · All Rights Reserved

We use cookies to ensure that we give you the best experience on our website. If you continue to use this site we will assume that you are happy with it.
You can revoke your consent any time using the revoke consent button.